A developer asks an AI coding agent to add an invoice viewer to an application. The agent produces working code quickly. It also adds invoice download, dispute and billing-address functions that were never approved.
The code compiles. The tests pass. The delivery is still wrong.
This is the governance problem that appears as coding agents become more autonomous. Traditional controls assume that people interpret requirements, read architecture standards, respect security boundaries and explain their decisions during review. An autonomous agent can move through those steps in minutes.
Our internal architecture work exposed the same pattern in several forms. Agents inferred scope, introduced inconsistent design choices, pulled sensitive information into model context, entered costly retry loops and produced changes that were difficult to review.
The answer is not more prompt engineering. Governance has to become executable and sit inside the software delivery path.
This article sets out a simple way to think about that shift: what must be controlled before code is generated, while the agent is running and before its change is accepted.
The control model has to move with the agent: govern intent before code, govern execution while it runs and govern evidence before the change is accepted.
At a glance
- Prompts are not reliable substitutes for approved requirements.
- Architecture and security guidance must become executable checks, not reference documents.
- Autonomous retries need runtime limits because cost and risk can grow before anyone reviews the result.
- A generated pull request should include evidence of what was built, why it was built and which controls passed.
Autonomy changes where governance has to sit
Conventional software delivery governance is built around human decision points. A product owner clarifies scope. An architect reviews the design. A developer follows security guidance. A reviewer checks the final change.
Coding agents compress these steps. Once an agent can inspect repositories, choose implementation paths, run tests and retry failures, governance applied only at the end becomes too late.
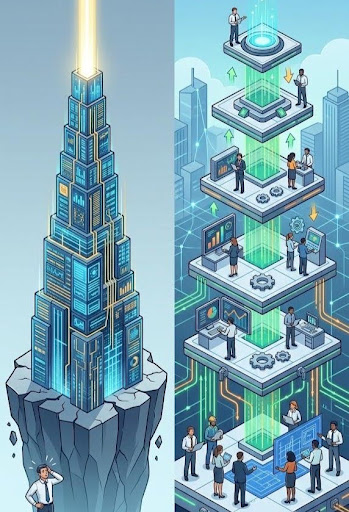
The practical shift is from review-based governance to execution-path governance. The controls still serve the same purpose. Their placement changes.
The control path has three stages:
- Before code: Validate the intent through an approved feature specification and executable architecture rules.
- During execution: Control the context, system access, retry behaviour and cost.
- Before acceptance: Require tests, policy results, traceability and a record of material decisions.
Before code: turn intent and architecture into executable inputs
The first weakness appears before generation starts. A coding agent treats ambiguity differently from a human engineer. When a ticket is incomplete, the agent may infer a plausible answer instead of asking for clarification.
In the invoice-viewer example, that can mean adding useful but unapproved functions. The technical output may be sound. The scope is not.
The control therefore begins with a machine-readable feature specification. The specification defines the approved outcome, boundaries and acceptance conditions. If the requirement is ambiguous, the workflow stops before code generation.
The same principle applies to architecture. Static standards are useful for people but weak as runtime controls. Agents need enforceable rules covering approved dependencies, repository structures, interface patterns and other non-negotiable constraints.
These rules can be implemented through templates, linters and policy checks within the build path.
The distinction is important: the feature specification tells the agent what it may build. Executable architecture rules constrain how it may build it.
During execution: control what the agent can see, spend and repeat
Autonomy creates risks that manual review cannot prevent because the damage can occur before a pull request exists.
Context is one example. An agent tracing a defect may inspect test fixtures, logs and environment variables. If sensitive information is allowed into the model context, a written instruction to avoid confidential data is not a control.
The execution path therefore needs inline inspection. Sensitive fields, credentials and restricted information can be masked or blocked before a request reaches the model endpoint.
Runtime economics require the same treatment. An autonomous agent can repeatedly modify code, run tests, fail and try again. A monthly cost report can show that the loop was expensive. It cannot stop the loop.
Useful runtime controls include:
- Bounded context windows
- Retry ceilings
- Time and consumption limits
- Feature-level cost attribution
- Escalation to a human when a boundary is exceeded
The objective is not to minimise every token. It is to make the reason, limit and outcome of the consumption visible.
Before acceptance: require evidence, not just working code
Faster generation moves the bottleneck downstream. Senior engineers can spend more time trying to reconstruct why an agent changed several files or chose a particular design path.
That makes evidence part of the deliverable. A generated change should arrive with:
- Traceability to the approved requirement
- Test results
- Architecture and security policy results
- A record of exceptions or failed checks
- A short explanation of material design decisions
The reviewer can then assess the decision and its supporting evidence instead of reverse-engineering the agent’s path from raw code alone.
This does not remove human review. It changes what the human reviews. Higher-risk changes can still require explicit approval. The agent should provide enough evidence to make that approval efficient and defensible.
What changes when governance enters the delivery path
Several familiar controls need to evolve as agent autonomy increases.
From detailed prompts to validated specifications
Detailed prompts and tickets still leave room for the agent to infer missing scope. A validated feature specification establishes what is authorised before generation begins.
From architecture guides to executable policies
An agent can interpret written guidance inconsistently. Repository templates, dependency rules and automated policy checks make the important constraints enforceable.
From security guidance to inline context controls
Sensitive information can enter the model context before anyone reviews the output. Context inspection and redaction must therefore happen during execution.
From monthly reporting to runtime boundaries
Usage reports explain expenditure after it has occurred. Runtime limits, cost attribution and escalation rules can intervene while the agent is still operating.
From code review to evidence-based acceptance
A reviewer should not have to reconstruct every agent decision from the generated code. The change should arrive with traceability, control results and an explanation of material choices.
The engineering implication is a control plane around the agent
A coding model is one component in the delivery system. The surrounding control plane determines:
- What work is authorised
- What context the agent may use
- Which systems and repositories it may access
- Which architecture rules are mandatory
- How long it may continue
- How much it may consume
- What evidence must exist before acceptance
This also helps preserve model portability. Requirements, architecture policy, security inspection and evidence should not be embedded only in prompts written for one model.
Keeping these controls outside the model makes it easier to change models without rebuilding the delivery process.
The same principle applies across greenfield, brownfield and legacy work. The individual boundaries will differ. The control structure remains similar.
What technology leaders should require before increasing agent autonomy
Define the control boundary
Specify what the agent may infer, which actions require approval and which enterprise rules must always be enforced outside the model.
Move critical checks into runtime
Identify controls that become ineffective if discovered only during manual review. Context leakage, runaway retries and unauthorised dependencies belong in this category.
Make evidence part of the acceptance criteria
Do not accept code alone as the output. Require traceability, test evidence, policy results and an explanation of material design decisions.
Increase autonomy in stages
An agent that can recommend a code change presents a different risk from one that can modify repositories, run deployment pipelines or access production systems. Expand autonomy only as the corresponding controls become operational.
Governance has to operate at the same speed as the agent
AI coding agents can compress software delivery steps that were previously separated by human decision points. That is useful. It also removes the pauses where many existing controls were applied.
The response should not be to slow the agent with more documents and manual gates. It should be to make the necessary controls executable at the points where scope, context, cost and design decisions are created.
The strongest coding model does not create a governed software delivery system. The control plane around it does.
Where are coding agents already making decisions inside your software delivery flow?
Bring us two or three software delivery workflows where coding agents are being introduced or given greater autonomy.
Ampersand can help identify which requirements, architecture rules, runtime controls and evidence checks need to move into the execution path.
Practical output: A focused control architecture for bounded, auditable AI-assisted software delivery.